TRAJECT-Bench
A trajectory-aware benchmark that checks how LLM agents select, parameterize, and order tool calls.


Why trajectories?
Agents increasingly rely on tools to finish real-world tasks, yet most benchmarks only grade the final answer. An agent can land on the right answer with a broken process, or fail because of one wrong argument early in a long chain. TRAJECT-Bench makes the tool-use trajectory itself the object of evaluation.
What’s inside
Production-style tools
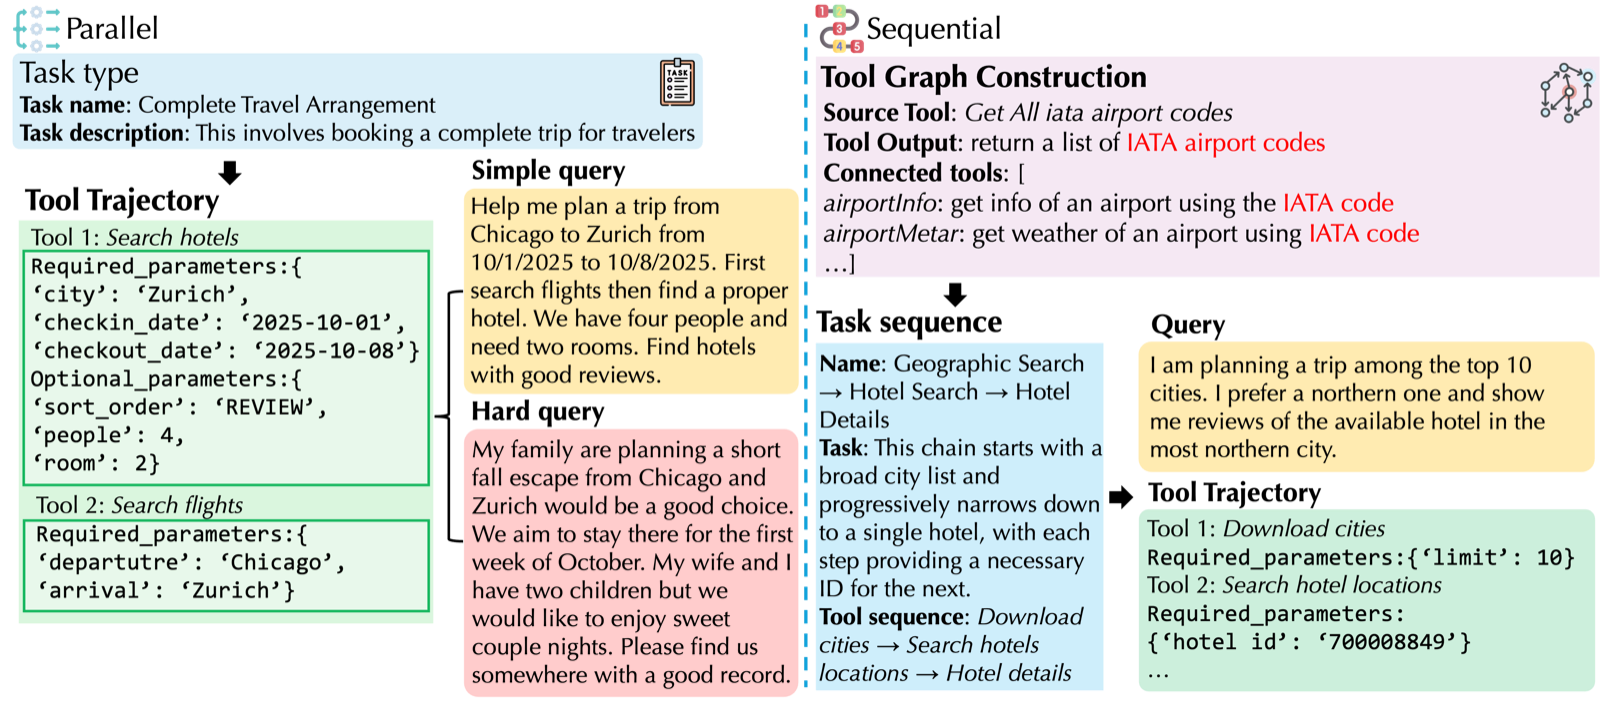
Over 1,000 high-fidelity, executable APIs across practical domains such as travel, finance, and music.
Breadth and depth
Parallel calls test breadth; interdependent sequential chains test depth.
Simple vs. hard queries
Every trajectory comes with an explicit query and an implicit one where the agent must infer the needed tools.
Trajectory-level metrics
Exact match, tool inclusion, argument correctness, dependency and order satisfaction, plus final accuracy.
Key findings
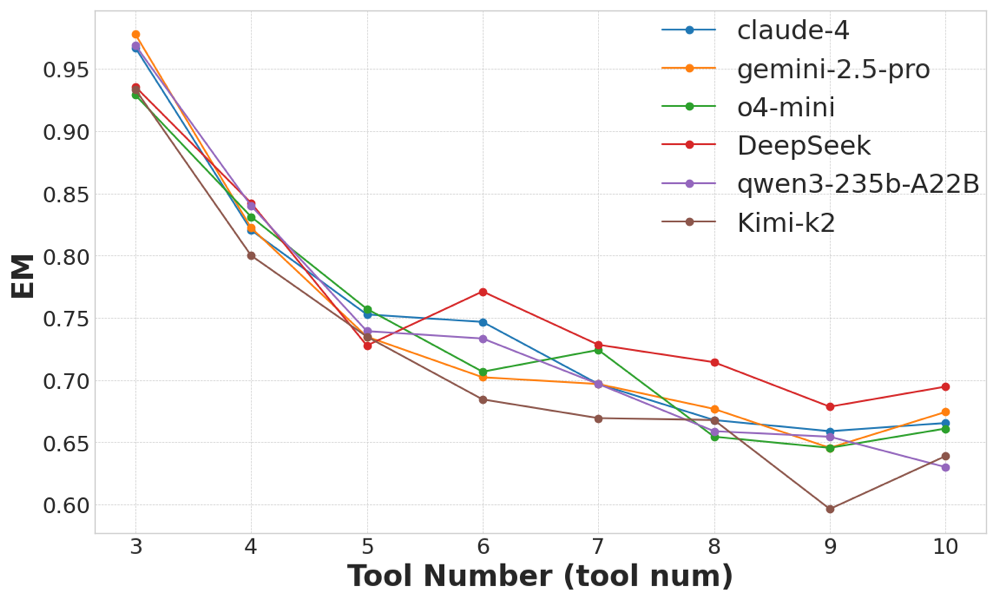
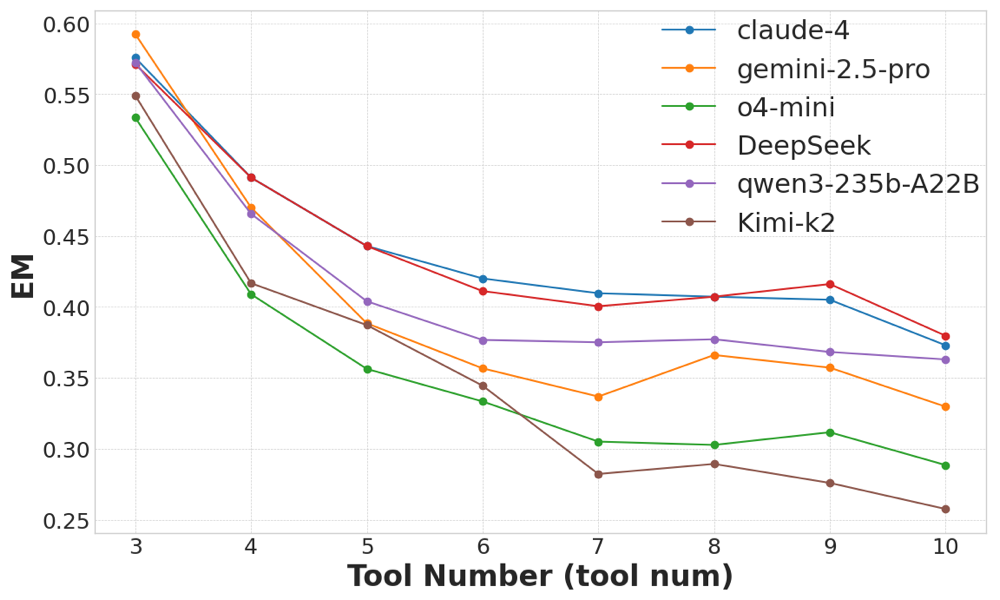
Scaling tool use is a universal challenge. Performance drops for every model as trajectories get longer, and the sharpest drop is the step from short to mid-length trajectories.
Implicit queries are hard. When the user does not name the steps, models struggle to infer which tools are needed, which causes cascading errors in selection and arguments.
Recurring failure modes. Models confuse similar tools and select tools without checking whether their parameters fit the request.
Retrieval is not a silver bullet. Retrieval-based tool selection helps little on simple queries and becomes a severe bottleneck on hard ones, while agentic methods such as ReAct with dynamic retrieval are more robust.
Get started
git clone https://github.com/PengfeiHePower/TRAJECT-Bench.git
cd TRAJECT-Bench
pip install -r requirements.txt
python evaluation/tool_evaluation_model.py -model claude_v37 -tool_select domain \
  -method direct -traj_type parallel -traj_file simple_ver
Citation
@inproceedings{he2026traject,
  title     = {TRAJECT-Bench: A Trajectory-Aware Benchmark for Evaluating Agentic Tool Use},
  author    = {He, Pengfei and Dai, Zhenwei and He, Bing and Liu, Hui and Tang, Xianfeng and
               Lu, Hanqing and Li, Juanhui and Ding, Jiayuan and Mukherjee, Subhabrata and
               Wang, Suhang and Xing, Yue and Tang, Jiliang and Dumoulin, Benoit},
  booktitle = {International Conference on Learning Representations (ICLR)},
  year      = {2026}
}